Category: Technology

Programming, gadgets (reviews thereof) and computers

The Third Way

macbook_airOperating Systems were the great religious divide of our age.

A little over a year ago I was writing about my experiences setting up my Sony Vaio Windows 8 laptop to run Ubuntu on a virtual machine. Today I am exploring the Third Way – I’m writing this on a MacBook Air. This is the result of a client requirement: I’m working with the Government Digital Service who are heavily Mac oriented.

I think this makes me a secularist in computing terms.

My impressions so far:

Things got off to a slightly rocky start, the MacBook I’m using is a hand-me-down from a departing colleague. We took the joint decision to start from scratch on this machine and as a result of some cavalier disk erasing we ended up with a non-booting MacBook. In theory we should have been able to do a reinstall over the internet, in practice this didn’t work. So off I marched to our local Apple Store to get things sorted. The first time I’d entered such an emporium. I was to leave disappointed, it turned out I needed to make an appointment for a “Genius” to triage my laptop and the next appointment was a week hence, and I couldn’t leave the laptop behind for a “Genius Triage”. Alternatively, I could call Apple Care.

As you may guess this Genius language gets my goat! My mate Zarino was an Apple College Rep – should they have called him a Jihadi? Could you work non-ironically with a job title of Genius?

Somewhat bizarrely, marching the Air to the Apple Store and back fixed the problem, and an hour or so later I had a machine with an operating system. Perhaps it received a special essence from the mothership. On successfully booting my first actions were to configure my terminal. For the initiated the terminal is the thing that looks like computing from the early 80s – you type in commands at a prompt and are rewarded with more words in return. The reason for this odd choice was the intended usage. This MacBook is for coding, so next up was installing Sublime Text. I now have an environment for coding which superficial looks like the terminal/editor combination I use in Windows and Ubuntu!

It’s worth noting that for the MacBook the bash terminal I am using is a native part of the operating system, as it is for the Ubuntu VM on Windows the bash terminal is botched on to make various open source tools work.

Physically the machine is beautiful. My Vaio is quite pretty but compared to the Air it is fat and heavy. It has no hard disk indicator light. It has no hard disk, rather a 256GB SSD which means it boots really fast. 256GB is a bit small for me these days, with a title of data scientist I tend to stick big datasets on my laptop.

So far I’ve been getting used to using cmd+c and cmd+v to copy and paste, having overwritten stuff repeatedly with “v” having done the Windows ctrl+v. I’m getting used to the @ and ” keys being in the wrong place. And the menu bar for applications always appearing at the top of the screen, not the top of the application window. Fortunately the trackpad I can configure to simulate a two button mouse, rather than the default one button scheme. I find the Apple menu bar at the top a bit too small and austere and the Dock at the bottom is a bit cartoony. The Notes application is a travesty, a little faux notebook although I notice in OS X Mavericks it is more business-like.

For work I don’t anticipate any great problems in working entirely on a Mac, we use Google Apps for email and make extensive use of Google Docs. We use online services like Trello, GitHub and Pivotal in place of client side applications. Most the coding I do is in Python. The only no go area is Tableau which is currently only available on Windows.

I’ve never liked the OS wars, perhaps it was a transitional thing. I grew up in a time when there were a plethora of home computers. I’ve written programs on TRS-80s, Commodore VIC20, Amstrad CPC464s, Sinclair ZX81 and been aware of many more. At work I’ve used Dec Alphas, VAX/VMS and also PCs and Macs. Latterly everything is one the web, so the OS is just a platform for a browser.

I’m thinking of strapping the Air and the Vaio back to back to make a triple booting machine!

Sublime

sublime_text

Sublime Text

Coders can be obsessive about their text editors. Dividing into relatively good natured camps. It is text editors not development environments over which they obsess and the great schism is between is between the followers of vim and those of Emacs. The line between text editor and development environment can be a bit fuzzy. A development environment is designed to help you do all the things required to make working software (writing, testing, compiling, linking, debugging, organising projects and libraries), whilst a text editor is designed to edit text. But sometimes text editors get mission creep.

vim and emacs are both editors with long pedigree on Unix systems. vim‘s parent, vi came into being in 1976, with vim being born in 1991, vim stands for “Vi Improved”. Emacs was also born in 1976. Glancing at the emacs wikipedia page I see there are elements of religiosity in the conflict between them.

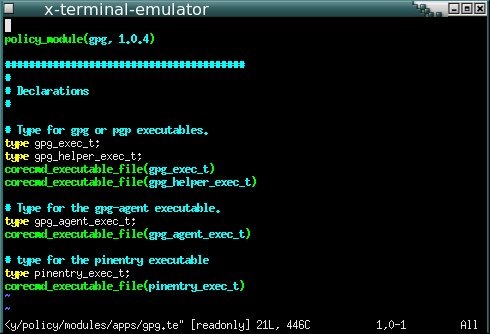
To users of OS X and Windows, vim and emacs look and feel, frankly, bizarre. They came into being when windowed GUI interfaces didn’t exist. In basic mode they offer a large blank screen with no icons or even text menu items. There is a status line and a command line at the bottom of the screen. Users interact by issuing keyboard commands, they are interfaces with only keyboard shortcuts. It’s said that the best way to generate a random string of characters is to put a class of naive computer science undergraduates down in front of vim and tell them to save the file and exit the program! In fact to demonstrate the point, I’ve just trapped myself in emacs  whilst trying to take a screen shot.

selinux_vim_0

vim, image by Hermann Uwe

GNU emacs-[1]

emacs, image by David Mundy

vim and emacs are both incredibly extensible, they’re written by coders for coders. As a measure of their flexibility: you can get twitter clients which run inside them.

I’ve used both emacs and vim but not warmed to either of them. I find them ugly to look at and confusing, I don’t sit in front on an editor enough of the day to make remembering keyboard shortcuts a comfortable experience. I’ve used the Matlab, Visual Studio and Spyder IDEs but never felt impassioned enough to write a blog post about them. I had a bad experience with Eclipse, which led to one of my more valued Stackoverflow answers.

But now I’ve discovered Sublime Text.

Sublime Text is very beautiful, particularly besides vim and emacs. I like the little inset in the top right of my screen which shows the file I’m working on from an eagle’s perspective, the nice rounded tabs. The colour scheme is subtle and muted, and I can get a panoply of variants on the theme. At Unilever we used to talk about trying to delight consumers with our products – Sublime Text does this. My only wish is that it went the way of Google Chrome and got rid of the Windows bar at the top.

Not only this, as with emacs and vim, I can customise Sublime Text with code or use other packages other people have written and in my favoured language, Python.

I use Sublime Text mainly to code in Python, using a Git Bash prompt to run code and to check it into source control. At the moment I have the following packages installed:

  • Package Control – for some reasons the thing that makes it easy to add new packages to Sublime Text comes as a separate package which you need to install manually;
  • PEP8 Autoformat – languages have style guides. Soft guidelines to ensure consistent use of whitespace, capitalisation and so forth. Some people get very up tight about style. PEP8 is the Python style guide, and PEP8 autoformat allows you to effortlessly conform to the style guide and so avoid friction with your colleagues;
  • Cheat Sheets – I can’t remember how to do anything, cheat sheets built into the editor make it easy to find things, and you can add your own cheat sheets too;
  • Markdown Preview – Markdown is a way  of writing HTML without all the pointy brackets, this package helps you view the output of your Markdown;
  • SublimeRope – a handy package that tells you when your code won’t run and helps with autocompletion. Much better than cryptic error messages when you try to run faulty code. I suspect this is the most useful one so far.
  • Git and GitGutter – integrating Git source control into the editor. Git provides all the Git commands on a menu whilst GitGutter adds markers in the margin (or gutter) showing the revision status. These work nicely on Ubuntu but I haven’t worked out how to configure them on Windows.
  • SublimeREPL – brings a Python prompt into the editor. There are some configuration subtleties here when working with virtual environments.

I know I’ve only touched the surface of Sublime Text but unlike other editors I want to learn more!

Face ReKognition

G8Italy2009

This post was first published at ScraperWiki. The ReKognition API has now been withdrawn.

I’ve previously written about social media and the popularity of our Twitter Search and Followers tools. But how can we make Twitter data more useful to our customers? Analysing the profile pictures of Twitter accounts seemed like an interesting thing to do since they are often the faces of the account holder and a face can tell you a number of things about a person. Such as their gender, age and race. This type of demographic information is useful for marketing, and understanding who your product appeals to. It could also be a way of tying together public social media accounts since people like me use the same image across multiple accounts.

Compact digital cameras have offered face recognition for a while, and on my PC, Picasa churns through my photos identifying people in them. I’ve been doing image analysis for a long time, although never before on faces. My first effort at face recognition involved using the OpenCV library. OpenCV provides a whole suite of image analysis functions which do far more than just detect faces. However, getting it installed and working with the Python bindings on a PC was a bit fiddly, documentation was poor and the built-in face analysis capabilities were poor.

Fast forward a few months, and I spotted that someone had cast the ReKognition API over the images that the British Library had recently released, a dataset I’ve been poking around at too. The ReKognition API takes an image URL and a list of characteristics in which you are interested. These include, gender, race, age, emotion, whether or not you are wearing glasses or, oddly, whether you have your mouth open. Besides this summary information it returns a list of feature locations (i.e. locations in the image of eyes, mouth nose and so forth). It’s straightforward to use.

But who should be the first targets for my image analysis? Obviously, the ScraperWiki team! The pictures are quite small but ReKognition identified I was a “Happy, white, male, age 46 with no glasses on and my mouth shut”. Age 46 is a bit harsh – I’m actually 39 in my profile picture. A second target came out “Happy, Indian, male, age 24.7, with glasses on and mouth shut”. This was fairly accurate, Zarino was 25 when the photo was taken, he is male, has his glasses on but is not Indian. Two (male) members of the team, have still not forgiven ReKognition for describing them as female, particularly the one described as a 14 year old.

Fun as it was, this doesn’t really count as an evaluation of the technology. I investigated further by feeding in the photos of a whole load of famous people. The results of this are shown in the chart below. The horizontal axis is someone’s actual age, the vertical axis shows their age predicted by ReKognition. If the predictions were correct the points representing the celebrities would fall on the solid line. The dotted line shows a linear regression fit to the data. The equation of the line y = 0.673x (I constrained it to pass through zero) tells us that the age is consistently under-predicted by a third, or perhaps celebrities look younger than they really are! The R2 parameter tells us how good the fit is: a value of 0.7591 is not too bad.

ReKognitionFacePeopleChart

I also tried out ReKognition on a couple of class photos – taken at reunions, graduations and so forth. My thinking here being that I would get a cohort of people aged within a year of each other. These actually worked quite well; for older groups of people I got a standard deviation of only 5 years across a group of, typically, 10 people. A primary school class came out at 16+/-9 years, which wasn’t quite so good. I suspect the performance here is related to the fact that such group photos are taken relatively carefully and the lighting and setup for each face in the photo is, by its nature, the same.

Looking across these experiments: ReKognition is pretty good at finding faces in photos, and not find faces where there are none (about 90% accurate). It’s fairly good with gender (getting it right about 80% of the time, typically struggling a bit with younger children), it detects glasses pretty well. I don’t feel I tested it well on race. On age results are variable, for the ScraperWiki set the R^2 value for linear regression between actual and detected ages is about 0.5. Whilst for famous people it is about 0.75. In both cases it tends to under-estimate age and has never given an age above 55 despite being fed several more mature celebrities and grandparents. So on age, it definitely tells you something and under certain circumstances it can be quite accurate. Don’t forget the images we’re looking at are completely unconstrained, they’re not passport photos.

Finally, I applied face recognition to Twitter followers for the ScraperWiki account, and my personal account. The Summarise This Data tool on the ScraperWiki Platform provides a quick overview of the data added by face recognition.

face_recognition_data

It turns out that a little over 50% of the followers of both accounts have a picture of a human face as their profile picture. It’s clear the algorithm makes the odd error mis-identifying things that are not human faces as faces (including the back of a London Taxi Cab). There’s also the odd sketch or cartoon of a face, rather than a photo and some accounts have pictures of famous people, rather than obviously the account holder. Roughly a third of the followers of either account are identified as wearing glasses, three quarters of them look happy. Average ages in both cases were 30. The breakdown in terms of race is 70:13:11:7 White:Asian:Indian:Black. Finally, my followers are approximately 45% female, and those of ScraperWiki are about 30% female.

We’re now geared up to apply this to lists of Twitter followers – are you interested in learning more about your followers? Then send us an email and we’ll be in touch.

The BIG Lottery Data

uklogo

This post was originally published at ScraperWiki.

The UK’s BIG Lottery Fund recently released its grant data since 2004 as a set of lovely CSV files: You can get it yourself here or here. I found it a great opportunity to try out some new tricks with Tableau, and have a bit of a poke around another largish dataset from government. The data runs to a little under 120,000 lines.

The first question to ask is: where is all the money going?

The total awarded is £5,277,058,180 over nearly 10 years. It’s going to 81,386 different organisations. The sizes of grants vary enormously; the biggest, £214,340,846, going to the Big Local Trust, which is an umbrella organisation. Other big recipients include the Royal Society of Wildlife Trusts, who received £59,842,400 for the Local Food programme. The top 10 grants are listed below:

01/03/2012, Big Local Trust  £        214,340,846
15/08/2007, Royal Society of Wildlife Trusts  £          59,842,400
04/10/2007, The Federation of Groundwork Trusts  £          58,306,400
13/05/2008, Sustrans Limited  £          49,980,908
11/10/2012, Life Changes (Trustee) Limited  £          49,338,186
13/12/2011, Forces In Mind Trustee Limited  £          34,808,423
19/10/2007, Natural England  £          30,113,200
01/05/2007, Legacy Trust UK Limited  £          28,850,000
31/07/2007, Sustrans Limited  £          25,023,084
09/04/2008, Falkirk Council  £          25,000,000

Awards like this make determining the true geographic distribution of grants a bit tricky, since they are registered as being awarded to a particular local area – apparently the head office of the applicant – but they are used nationally. There is a regional breakdown of where the money is spent but this classification is to large areas i.e. “England” or “North West”. The Big Local Trust, Life Changes and Forces in Mind are all very recently established – less than a couple of years old. The Legacy Trust was established in 2007 to fund programmes to promote an Olympic legacy.

These are really big grants, but what does the overall distribution of awards look like?

This is shown in the chart below:

Award distribution

It’s a bit complicated because the spread of award sizes is from about £1000 to over £100,000,000 so what I’ve done is taken the logarithm of the award to create the bins. This means that the column marked “3” contains the sum of all awards from £1000 to £9999 and that marked “4” contains the sum of all awards from £10,000 to £99,999. The chart shows that most money is distributed in the column marked “5”, i.e. £100,000 to £999,999. The columns are coloured by the year in which money was awarded, so we can see that there were large grants awarded in 2007 as well as 2011 and 2013.

Everybody loves a word cloud, even though we know it’s not good in terms of data visualisation, a simple bar chart shows the relative frequency of words more clearly. The word cloud below shows the frequency of words appearing in the applicant name field of the data, lots of money going to Communities, Schools, Clubs and councils.

image

The data also include the founding date for the organisations to which money is awarded, most of them were founded since the beginning of the 20th century. There are quite a few schools and local councils in the list and, particularly for councils we can see the effect of legislation on the foundation of these organisations, there are big peaks in founding dates for councils in 1894 and in 1972-1974, coinciding with a couple of local government acts. There’s a dip in the foundation of bodies funded by the BIG lottery for both the First and Second World Wars, I guess people’s energies were directed elsewhere. The National Lottery started in the UK in late 1994.

Founding year

As a final piece of analysis I thought I’d look at sport; I’m not particularly interested in sport so I let natural language processing find sports for me in applicant names – they are often of the form “Somewhere Cricket/Rugby/Tennis/etc Club”. One way of picking out all the sports awards would be to come up with a list of sports names and compare against that list but I applied a little more cunning: the nltk library will tell you how closely related two words are using the WordNet lexicon which it contains. So I identified sports by measuring how closely related a target word was from the word “sport”. This got off to a shaky start  since I decided to use “cricket” as a test word; “cricket” is as closely related to “sport” as “hamster” – a puzzling result until I realised that the first definition of “cricket” in WordNet relates to the insect! This confusion dispensed with finding all the sports mentioned in the applicant names was an easy task. The list of sports I ended up with was unexceptional.

You can find participation levels in various sports here, I plotted them together with numbers of awards. Sports near the top left have relatively few awards given the number of participants, whilst those bottom right have more awards than would be expected from the number of participants.


Number of clubs vs number of participants

You can see interactive versions of these plots, plus a view more here on Tableau Public.

That’s what I found in the data – what would interest you?

Footnotes

I uploaded the CSV files to a MySQL database before loading into Tableau, I also did a bit of work in Python using the pandas library. In addition to the BIG lottery data I pulled in census data from the ONS and geographic boundary data from Tableau Mapping. You can see all this unfolding on the bitbucket repo I set up to store the analysis. Since Tableau workbook files are XML format they can be usefully stored in source control.

Git!

logo@2x

This post was first published at ScraperWiki.

As software company, use of some sort of software source control system is inevitable, indeed our CEO wrote TortoiseCVS – a file system overlay for the early CVS source control system. For those uninitiated in the joys of software engineering: source control is a system for recording the history of file revisions allowing programmers to edit their code, safe in the knowledge that they can always revert to a previous good state of code if it all goes horribly wrong. We use Git for source control, hosted either on Github or on Bitbucket. The differing needs of our platform and data services teams fit the payment plans of the two different sites.

Git is a distributed source control system created by Linus Torvalds, to support the development of Linux. Git is an incredibly flexible system which allows you to do pretty much anything. But what should you do? What should be your strategy for collective code development? It’s easy to look up a particular command to do a particular thing, but less is written on how you should string your git commands together. Here we hope to address this lack.

We use the “No Switch Yard” methodology, this involves creating branches from the master branch on which to develop new features and regularly rebasing against the master branch so that when the time comes the feature branch can be merged into the master branch via a pull request with little fuss. We should not be producing a byzantine system by branching feature branches from other feature branches. The aim of “No Switch Yard” is to make the history as simple as possible and make merging branches back onto master as easy as possible.

How do I start?

Assuming that you already have some code in a repository, create a local clone of that repository:

git clone git@github.com:scraperwiki/myproject.git

Create a branch:

git checkout -b my-new-stuff

Start coding…adding files and committing changes as you go:

git add -u
git commit -m "everything is great"

The -u switch to git add simply checks in all the tracked, uncommitted files. Depending on your levels of paranoia you can push your branch back to the remote repository:

git push

How do I understand what’s going on?

For me the key revelation for workflow was to be able to find out my current state and feel pleasure when it was good! To do this, fetch any changes that may have been made on your repository:

git fetch

and then run:

git log --oneline --graph --decorate --all

To see an ASCII art history diagram for your repository. What you are looking for here is a relatively simple branching structure without too many parallel tracks and with the tips of each branch lined up between your local and the remote copy.
You can make an alias to simplify this inspection:

git config --global alias.lg 'log --oneline --graph --decorate'

Then you can just do:

git lg --all

I know someone else has pushed to the master branch from which I branched – what should I do?

If stuff is going on on your master branch, perhaps because your changes are taking a while to complete, you should rebase. You should also do this just before submitting a pull request to merge your work with the master branch.

git rebase -i

Allows you to rebase interactively, this means you can combine multiple commits into a single larger commit. You might want to do this if you made lots of little commits whilst achieving a single goal. Rebasing brings you up to date with another branch, without actually merging your changes into that branch.

I’m done, how do I give my colleagues the opportunity to work on my great new features?

You need to rebase against the remote branch onto which you wish to merge your code and then submit a pull request for your changes. You can submit a pull request from the web interface at Github or Bitbucket. Or you can use a command line tool such as hub.  The idea of using a pull request is that it makes your changes visible to your colleagues, and keeps a clear record of those changes. If you’ve been rebasing regularly you should be able to merge your code automatically.

An important principle here is “ownership”, in social terms you own your local branch on which you are developing a feature, so you can do what you like with it. The master branch from which you started work is in collective ownership so you should only merge changes onto it with the permission of your colleagues and ideally you want others to look at your changes and approve the pull themselves.

I started doing some fiddling around with my code and now I realise it’s serious and I want to put it on a branch, what did I do?

You need to stash your code, using:

git stash

Then create a branch, as described above, and then retrieve the contents of the stash:

git stash pop

That’s how we use git – what do you do?